Ronak Makwana.
Engineering reliable connections between data, systems and intelligence.
I build data, integration and AI solutions on Microsoft Azure—with a focus on practical architecture, dependable pipelines and systems that are easier to operate.
Built around real engineering problems.
These portfolio initiatives are planned. Completed implementations, source code and validated results will be linked as they become available.
Metadata-driven data platform
A reusable ingestion design for Azure Data Factory and ADLS Gen2, with incremental loads, run logging and recovery paths.
Event-driven enterprise integration
A reference design for connecting business systems through durable messaging, resilient APIs and observable workflows.
Fabric analytics & applied AI
A portfolio direction exploring governed lakehouse analytics and useful AI experiences grounded in enterprise data.
From ingestion to insight.
Azure Data Engineering
Data Factory, Databricks, ADLS Gen2, PySpark and dependable batch pipelines.
Enterprise Integration
API and workflow patterns, system connectivity and resilient message processing.
Microsoft Fabric
Lakehouse architecture, data orchestration and governed analytics.
Streaming
Event-driven architecture, real-time ingestion and replay-aware processing.
Applied AI
Practical AI integrations with attention to data quality, access and evaluation.
DevOps
Versioned infrastructure, delivery automation, monitoring and operational reliability.
Technology in a business context.
Architecture interests across industries—not a list of claimed client engagements.
Understand the decisions behind the design.
Security, observability and recovery belong across every stage. Explore published implementation guides and troubleshooting studies:
 Architecture decision
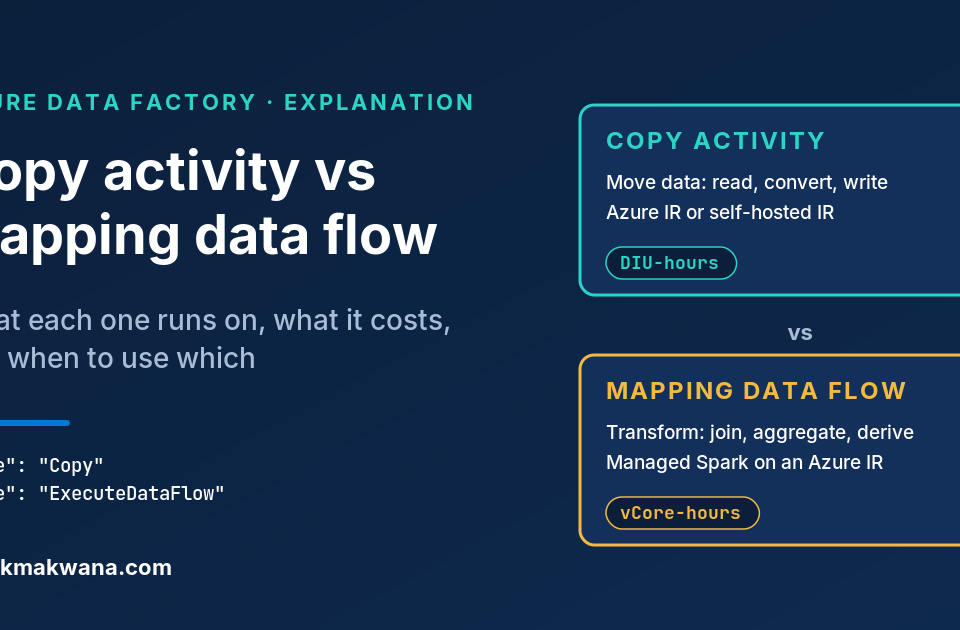
Copy or transform?
Choose the right execution pattern for Azure Data Factory.
 Troubleshooting study
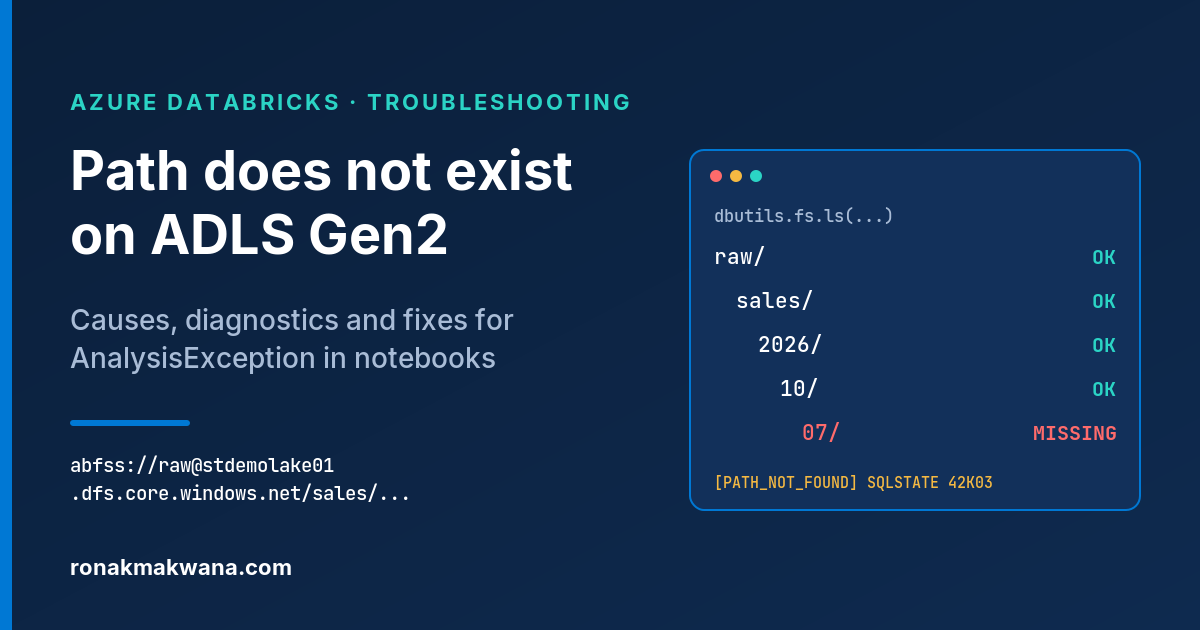
Find the missing path
Diagnose ADLS Gen2 path failures in Databricks notebooks.
 Implementation guide
Handle schema drift
Keep changing source schemas from breaking Parquet delivery.
Latest engineering notes
Practical Azure tutorials, architecture decisions and lessons from troubleshooting.
- ADF Copy Activity vs Mapping Data Flow: When to Use Which
 Copy activity moves data; mapping data flows transform it on managed Spark. How they differ on runtimes, connectors, transformations, tuning, billing, schema drift and debugging, how they combine, and a decision guide for choosing.
- Databricks Notebook Fails with AnalysisException: Path Does Not Exist on ADLS Gen2 — Causes and Fixes
 Fix [PATH_NOT_FOUND] Path does not exist errors when a Databricks notebook reads ADLS Gen2: what the error means, how to find the first wrong path segment, and fixes for abfss URIs, globs, late files, mounts and Unity Catalog volumes.
- How to Fix ADF Mapping Data Flows That Break on Schema Drift When Writing Parquet to ADLS Gen2
 Make an Azure Data Factory mapping data flow survive new, renamed and retyped columns when landing Parquet in ADLS Gen2: source settings, byName(), column patterns, sink mapping and Parquet naming rules.
Practical engineering.
Shared openly.
I’m an experienced Azure Data & Integration Engineer focused on building data, integration and AI solutions on Microsoft Azure. I share clear implementation notes, architecture tradeoffs and practical fixes to help other engineers build with confidence.
Have a data or integration challenge?
Connect to discuss Azure engineering, technical collaboration or an idea worth building.